Spark-X2.6-4B Benchmarks: A 4B Open Model Claiming 62.8% on SWE-bench Verified, Charted Against Qwen3.5 and Gemma4
XHToken’s Spark-X2.6-4B (Apache 2.0, 19 Oct 2026) averages 63.3 across 33 vendor-run benchmarks vs 49.1 for Qwen3.5-9B. Coding, agent, long-context results charted, where it loses, and whether it fits a 16 GB GPU.
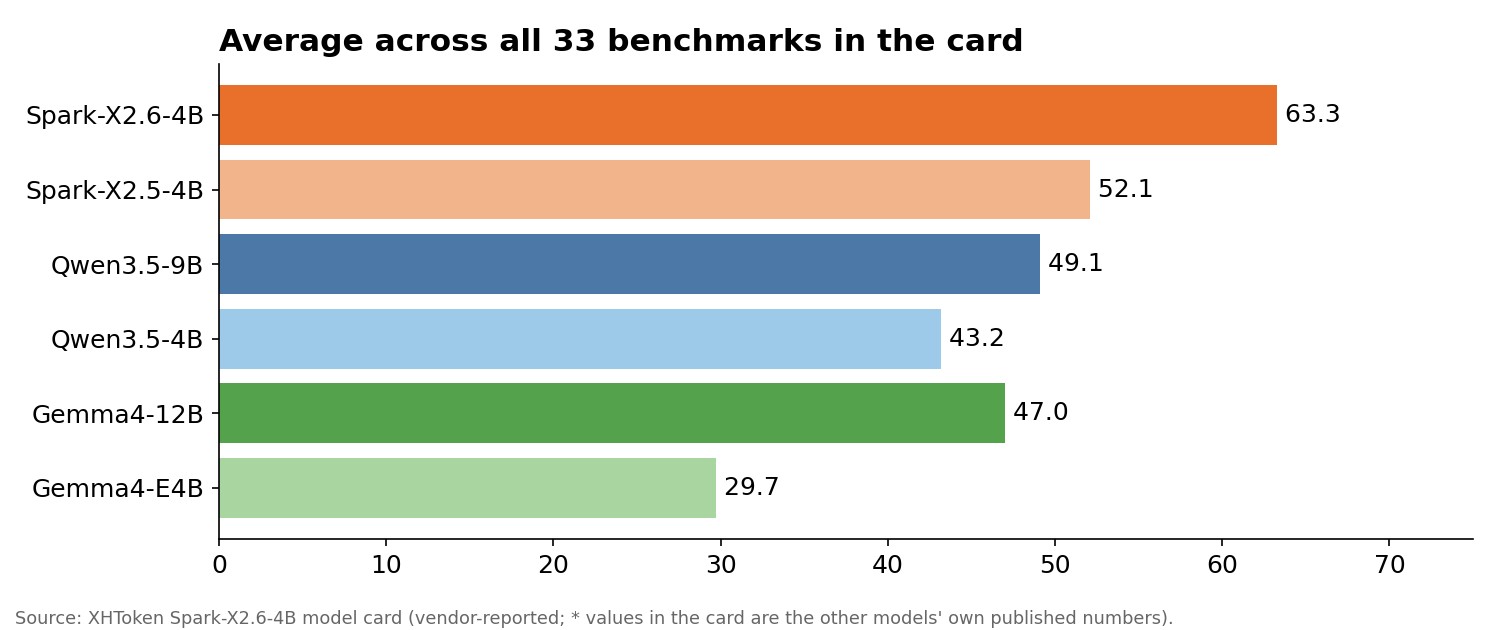
TL;DR — XHToken released Spark-X2.6-4B on Hugging Face on 19 October 2026. It is a 4-billion-parameter open model under Apache 2.0, with a context window of up to about 1 million tokens and official GGUF files (Q4_K_M is 3.54 GB). The vendor's own table puts it ahead of every model it compares against, including Qwen3.5-9B and Gemma4-12B. It averages 63.3 across 33 benchmarks, against 49.1 for Qwen3.5-9B. The standout numbers are SWE-bench Verified 62.8% and SWE-bench Pro 54.3%. It still trails Qwen3.5-9B on GPQA, long-context recall and LongBench. Every score below is vendor-reported, and nobody has reproduced them yet.
The model in one table
| Spark-X2.6-4B | |
|---|---|
| Developer | XHToken |
| On Hugging Face | 19 Oct 2026 |
| Parameters | ~4B, dense |
| Architecture | Same as Spark-X2.5-4B. The gains come from post-training. The config mixes sliding-window and full attention layers (3:1) |
| Context | Up to 1,048,576 tokens in the official server examples ("requires sufficient device memory") |
| Thinking modes | none / low / high (benchmarks run at high) |
| Languages | English, Chinese |
| Licence | Apache 2.0 |
| Official GGUF | Q4_K_M 3.54 GB, Q8_0 4.38 GB, BF16 8.23 GB |
| Runs in | llama.cpp (build b10828+), Ollama 0.34.1+, LM Studio 0.4.0+, vLLM, SGLang |
| Recommended sampling | temperature 1.0, top_p 0.95, top_k −1 |
A Korean summary that circulated today lists the Q4_K_M file at 3.19 GB. The file actually on Hugging Face is 3.54 GB.
How to read the leaderboard
All numbers come from the model card. Before treating them as a ranking, keep three things in mind:
- Vendor-run. XHToken ran its own model. Values marked * in the card are taken from the other models' published cards, so settings may differ.
- Two benchmarks are in-house. SWebBench and PAgentBench are XHToken's own tests and are "to be open-sourced soon". We leave them out of the charts.
- Thinking at "high". Spark ran at its highest reasoning setting, which costs more tokens and time per answer.
Coding
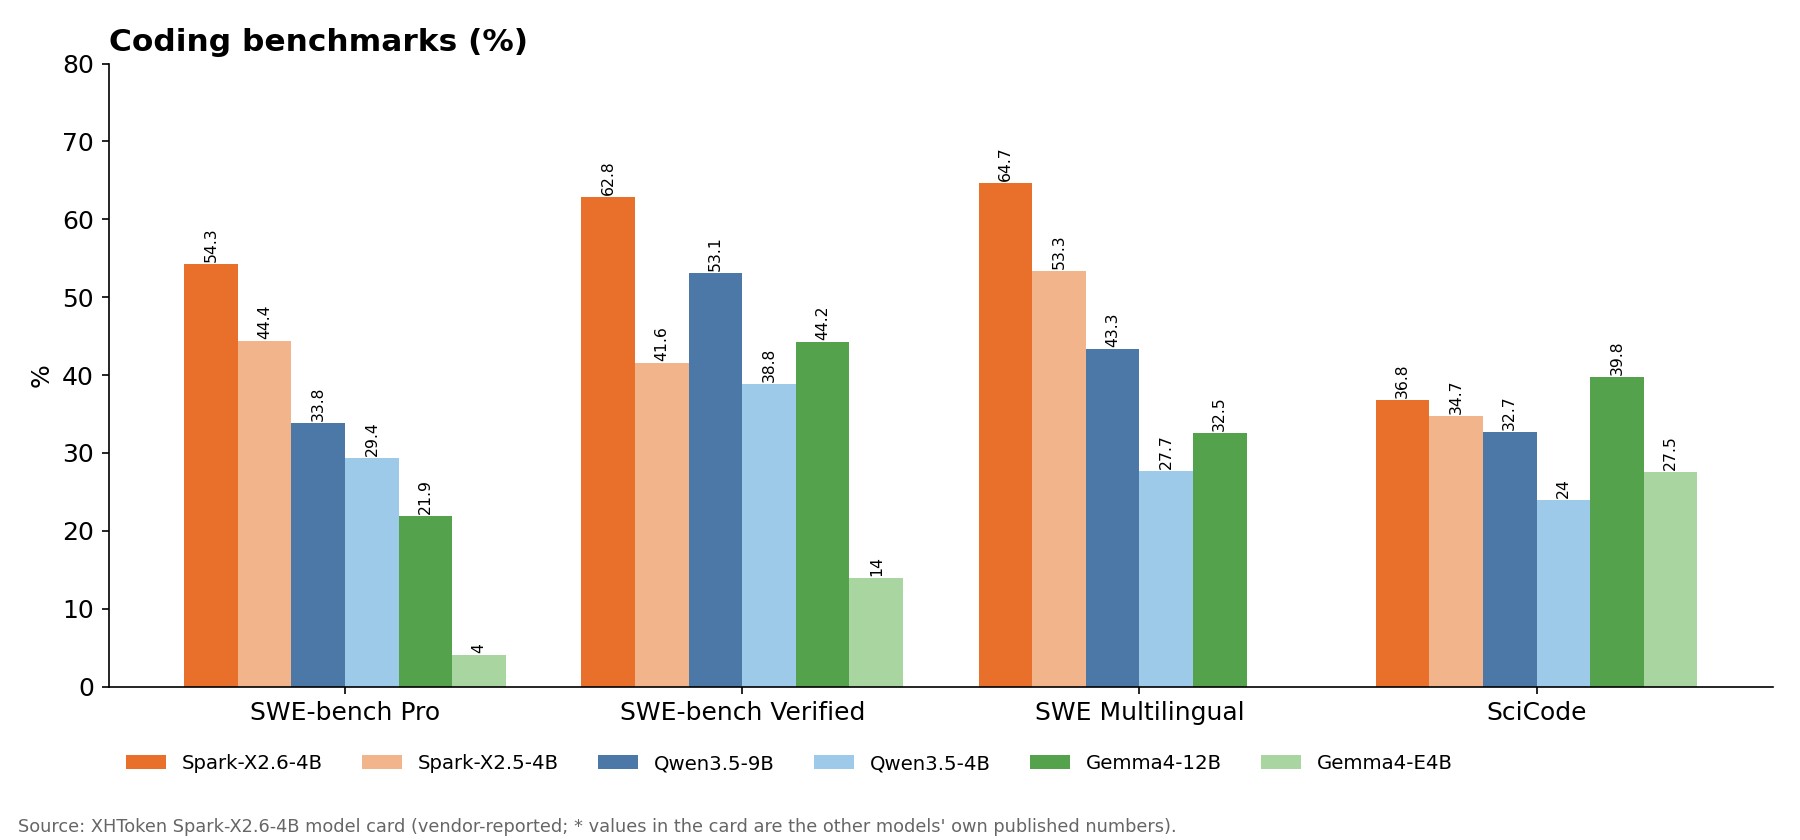
| Benchmark | Spark-X2.6-4B | Spark-X2.5-4B | Qwen3.5-9B | Qwen3.5-4B | Gemma4-12B | Gemma4-E4B |
|---|---|---|---|---|---|---|
| SWE-bench Pro | 54.3 | 44.4 | 33.8* | 29.4* | 21.9* | 4.0* |
| SWE-bench Verified | 62.8 | 41.6 | 53.1* | 38.8* | 44.2* | 14.0* |
| SWE Multilingual | 64.7 | 53.3 | 43.3 | 27.7 | 32.5* | – |
| SciCode | 36.8 | 34.7 | 32.7* | 24.0 | 39.8 | 27.5 |
The jump from X2.5 to X2.6 is the headline: +21.2 points on SWE-bench Verified with the same architecture. A 4B model at 62.8% Verified would be remarkable. It is also exactly the kind of number that needs an independent run before you rely on it, because harness, retries and time limits move SWE-bench scores a lot.
Agents and tool use
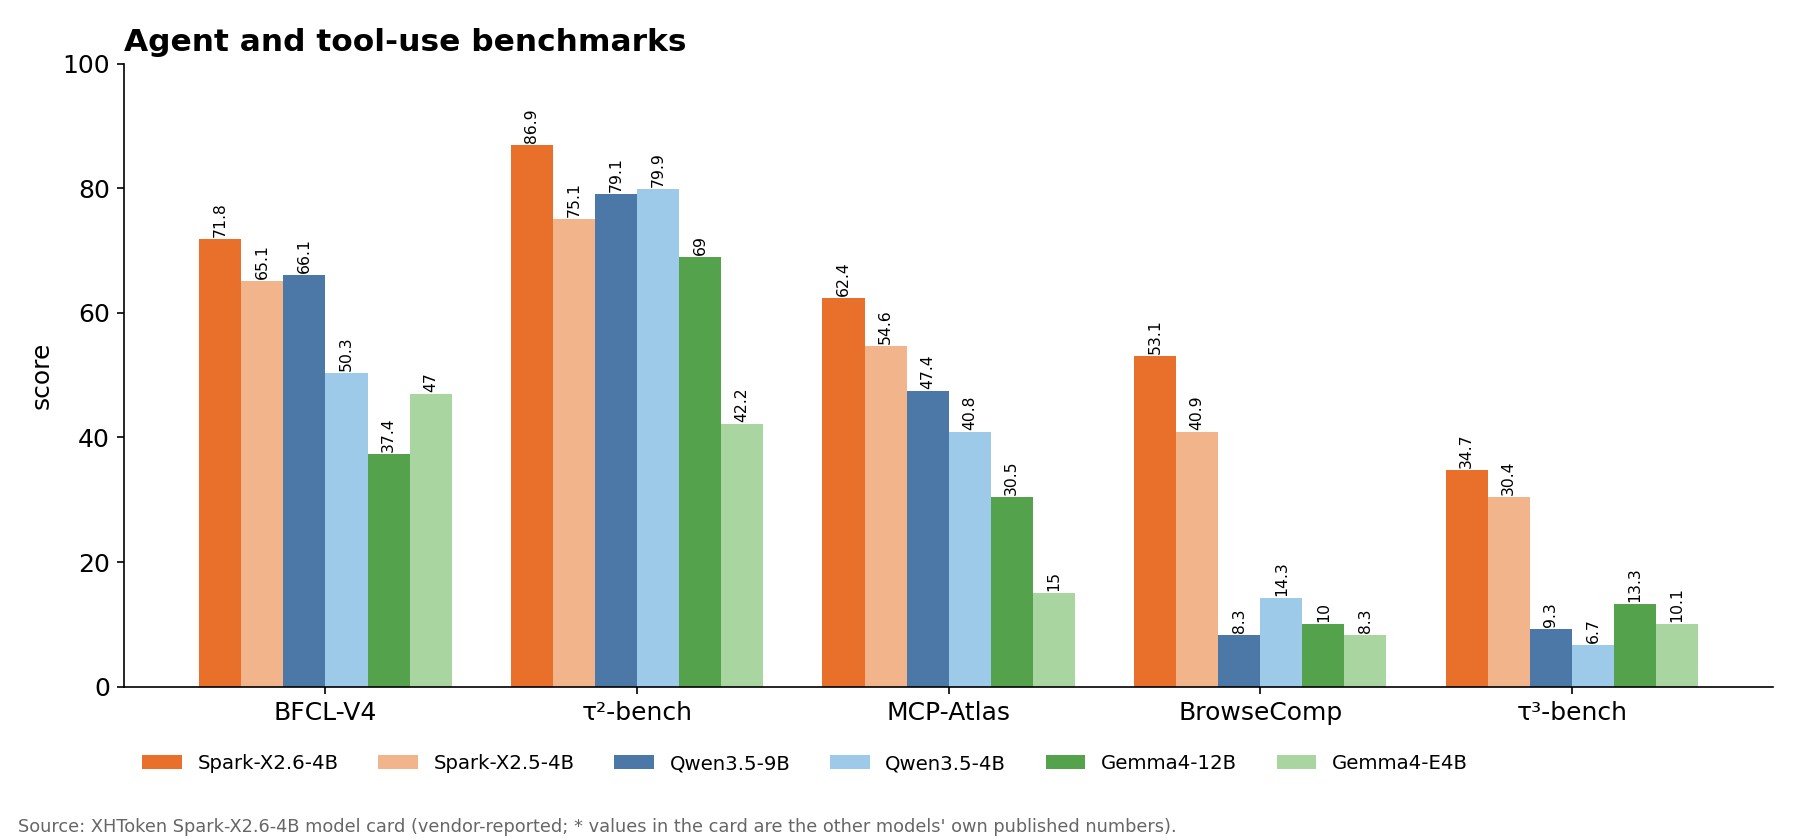
| Benchmark | Spark-X2.6-4B | Spark-X2.5-4B | Qwen3.5-9B | Qwen3.5-4B | Gemma4-12B | Gemma4-E4B |
|---|---|---|---|---|---|---|
| BFCL-V4 (function calling) | 71.8 | 65.1 | 66.1* | 50.3* | 37.4 | 47.0* |
| τ²-bench | 86.9 | 75.1 | 79.1* | 79.9* | 69.0* | 42.2* |
| τ³-bench | 34.7 | 30.4 | 9.3 | 6.7 | 13.3 | 10.1 |
| MCP-Atlas | 62.4 | 54.6 | 47.4* | 40.8* | 30.5* | 15.0* |
| EnterpriseOps-Gym | 33.6 | 27.3 | 24.7 | 22.9 | 24.5 | 8.6 |
| ClawEval-EN | 69.9 | 66.2 | 66.5* | 62.3* | 58.3 | 58.0* |
| BrowseComp | 53.1 | 40.9 | 8.3 | 14.3 | 10.0 | 8.3 |
| VitaBench 2.0 | 30.8 | 25.2 | 15.6 | 18.2 | 12.4 | 4.8 |
The biggest gaps are on BrowseComp (53.1 vs 8–14 for the others) and τ³-bench. Both measure long, multi-step tool use, which is what the model card says the post-training targeted.
Where it does not win
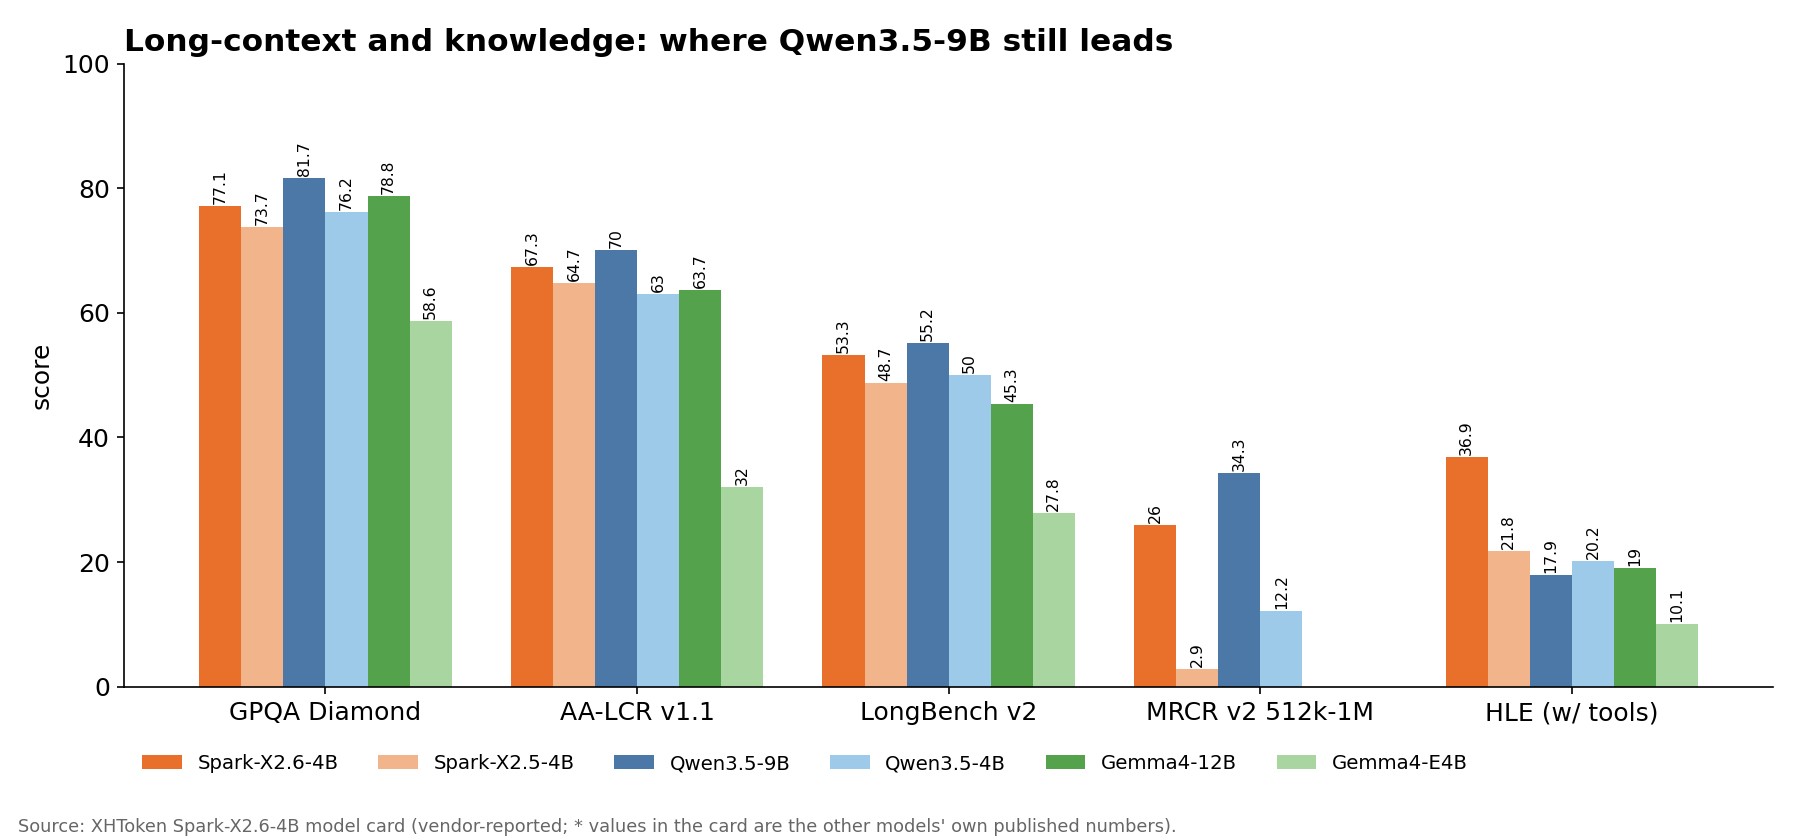
| Benchmark | Spark-X2.6-4B | Best other | Who |
|---|---|---|---|
| GPQA Diamond | 77.1 | 81.7* | Qwen3.5-9B |
| GPQA | 69.9 | 77.2 | Qwen3.5-9B |
| AA-LCR v1.1 (long-context reasoning) | 67.3 | 70.0* | Qwen3.5-9B |
| LongBench v2 | 53.3 | 55.2* | Qwen3.5-9B |
| OpenAI MRCR v2, 512k–1M | 26.0 | 34.3 | Qwen3.5-9B |
| IFEval | 93.6 | 94.8 | Gemma4-12B |
| SciCode | 36.8 | 39.8 | Gemma4-12B |
| Gaokao 2026 math (out of 150) | 134.9 | 135.5 | Qwen3.5-9B |
Two takeaways:
- Knowledge still scales with size. On GPQA a 9B model keeps its lead, as you'd expect.
- "1M context" is not "1M recall". At 512k–1M tokens, Spark finds the right item about a quarter of the time (MRCR 26.0). It improved enormously over X2.5 (2.9), but the window is much larger than what it can reliably use.
Spark does lead on HLE with tools (36.9 vs 21.8 for X2.5), AIME 2026 (91.2), HMMT Feb 26 (81.3) and IMO-AnswerBench (75.2).
Can it run on a 16 GB GPU?
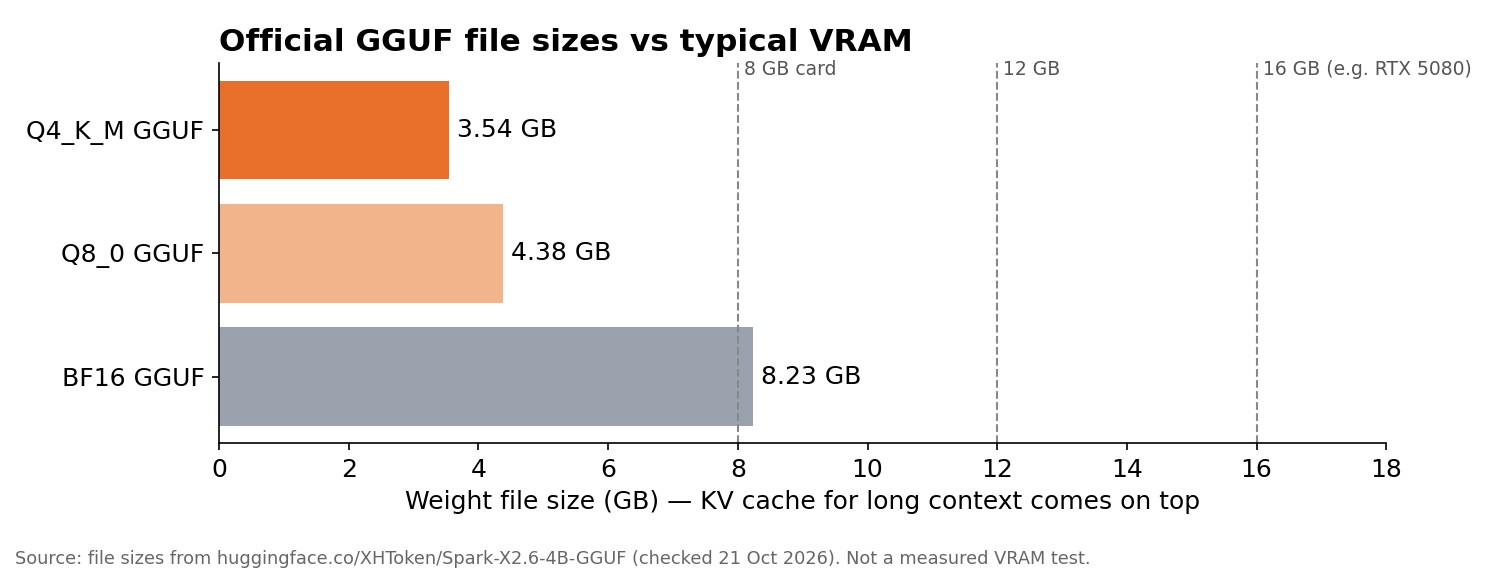
By file size alone, yes, easily:
| File | Size | Fits 8 GB? | Fits 16 GB (e.g. RTX 5080)? |
|---|---|---|---|
| Q4_K_M | 3.54 GB | Yes, with room for context | Yes |
| Q8_0 | 4.38 GB | Yes, short context | Yes, with plenty of context |
| BF16 | 8.23 GB | No | Yes, but long context will crowd it |
The weights are only part of the memory bill. The KV cache grows with context length, so 8k or 32k context is comfortable on a 16 GB card, while hundreds of thousands of tokens are not. We have not measured VRAM or speed ourselves.
XHToken's card includes a speed chart for an RTX 4090 (llama.cpp Q4_K_M and TensorRT INT4) and a Mac M5 Pro (llama.cpp and MLX). It publishes only curves, not exact numbers, so we don't quote them.
Quick start with the official GGUF:
llama-server -hf XHToken/Spark-X2.6-4B-GGUF:Q8_0 -c 8192
Verdict
- As a leaderboard entry: on its own table, the strongest open ~4B model by a wide margin, beating 9B and 12B models on coding and agent tasks.
- As something to use today: worth a try as a fast local helper for scoped jobs: single-file fixes, JSON and config edits, tool-calling scripts, log triage. It is small enough to run alongside other work on a 16 GB card.
- What to wait for: independent SWE-bench and agent runs, and the release of the two in-house benchmarks. Until then, the 62.8% Verified figure is a claim, not a result.
FAQ
Is Spark-X2.6-4B better than Qwen3.5-9B? On XHToken's table, yes on average (63.3 vs 49.1) and on coding and agent tasks. Qwen3.5-9B still wins on GPQA, long-context recall and LongBench v2.
Is it open source? The weights are open under Apache 2.0, including official GGUF files. Training data and recipe are not published.
What GPU do I need? Q4_K_M is 3.54 GB and Q8_0 is 4.38 GB, so an 8 GB card can run it at short context. A 16 GB card handles Q8_0 or even BF16 with room for a longer context.
Has anyone verified the SWE-bench score? Not as of 21 October 2026. All numbers are the vendor's own.
Sources: Spark-X2.6-4B model card (benchmark tables and inference chart in the card's images, read 21 Oct 2026), official GGUF repository, Hugging Face API for the upload date and file sizes. Charts are ours, drawn from the card's numbers.
← Back to all posts